Most data science teams discover the hard way that a working notebook and a production ML system are not the same thing. The model runs. The results look good. Then someone asks to deploy it, retrain it on a schedule, audit its training data, or run it in three environments simultaneously, and the infrastructure that was never really designed collapses under the weight of requirements it was never built to meet. Training is roughly 15% of the effort in a production ML system; the rest is infrastructure, governance, monitoring, and the plumbing that holds it together.
Getting data science platform architecture right from the start means making deliberate choices about environment parity, data residency, reproducibility, and the managed services that carry operational load your team should not be carrying itself. This post walks through how to structure that platform and where the decisions that look small early on become expensive later.
The notebook-to-production gap is an infrastructure problem
Most ML discussions centre on model quality. The harder problem is that a model trained in a data scientist’s local environment, against a snapshot of data, with library versions that are nowhere documented, cannot be reliably reproduced six months later. It cannot be audited. It cannot be safely promoted through dev, staging, and production without someone manually recreating conditions that were never formally captured.
The fix is to treat the entire ML workflow as a code-defined pipeline. Infrastructure-as-Code tools like Terraform define and manage the environments programmatically, so dev, staging, and production are not approximations of each other but provably identical configurations, version-controlled alongside the model code itself. Every dependency, every access control, every external table definition lives in a repository. Drift becomes detectable rather than invisible.
Separation of concerns matters as much as version control. Data preparation, storage, access interfaces, and consumption layers should be clearly delineated so that a change in one layer does not silently break another. In a well-structured platform, data flows unidirectionally from upstream sources through preparation and storage into downstream consumption. That unidirectional contract is what makes the system testable and the impact of changes local rather than global.
Multi-environment complexity is real and underestimated
Moving from a single environment to a governed multi-stage setup is where most teams hit their first serious infrastructure wall. Dev, staging, and production need to share enough structure to make promotion meaningful, but differ enough to protect production data and control costs. Maintaining consistent data governance across all three, while also handling the operational surface of the services that underpin them, is a significant ongoing burden.
The choice of training pattern influences everything downstream: compute footprint, cost profile, monitoring components, and incident runbooks. A project optimized for quarterly retraining will have different infrastructure than one designed for hourly model refreshes.
Managed services for databases, message queues, object storage, and data processing reduce that burden substantially. When the database patching, Redis scaling, and object storage replication are handled at the platform level, your team is spending time on model logic and pipeline design rather than on operational maintenance that adds no scientific value. The key is choosing managed services that are genuinely integrated, not a collection of loosely coupled third-party tools that each introduce their own failure modes and access control models.
CI/CD pipelines for ML are not optional in a multi-environment setup. Model promotion should be gated: a model moves from dev to staging only after automated tests pass against a defined dataset; it moves to production only after staging validation clears. Version control covers not just code but model artifacts, dataset versions, and the metadata schemas that describe them. Without that discipline, the audit trail that regulators and internal governance teams will eventually ask for does not exist.
Data residency and sovereignty are not the same contract
European data science teams working with personal data, healthcare records, or regulated financial data need to understand a distinction that gets blurred in most cloud vendor marketing: data residency tells you where data is stored; data sovereignty determines who controls access to it and under which legal jurisdiction.
A model trained on personal data in a Frankfurt data centre operated by a US-headquartered cloud provider satisfies geographic residency requirements. It does not satisfy sovereignty requirements, because that provider remains subject to US extraterritorial law. The CJEU’s Schrems II judgment made clear that controllers using Standard Contractual Clauses must assess whether the destination country’s legal framework provides essentially equivalent protection to GDPR. A contract clause cannot override a statute that compels disclosure.
The EU AI Act adds a further layer. High-risk AI systems must comply with Article 10, which requires training, validation, and testing datasets to be relevant, sufficiently representative, and as free of errors as possible, with documented data governance covering collection, origin, preparation, labelling, and quality assurance. Full data lineage tracking is not a nice-to-have; it is an enforceable requirement for systems that fall under the high-risk classification, with full enforcement for those systems applying from August 2026.
We operate under Tier III, carrier-neutral infrastructure certified to ISO 27001, with a contractual 99.9% uptime SLA and data residency enforced at the contract level, not just as a configuration option that can be changed by a support ticket. Sovereignty, in our case, is an architectural fact: the infrastructure is European, the legal jurisdiction is European, and the obligations run to European law.
Structuring the platform: practical layers
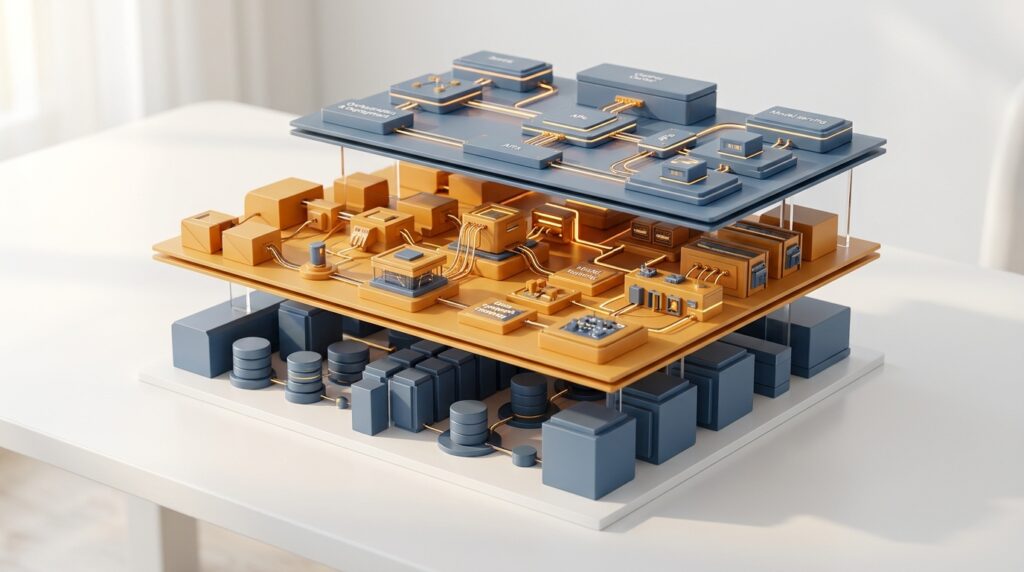
A reproducible, multi-environment data science platform needs to be thought of in layers, each with a clear owner and a clear interface to the layers adjacent to it.
- Compute layer: VPS or bare metal nodes sized to workload, with GPU capacity available for training jobs that need it. Separate compute pools for dev, staging, and production prevent resource contention and make cost attribution straightforward.
- Storage layer: Object storage for datasets and model artifacts, block storage for high-throughput workloads, with versioning enabled so that every training run can be traced back to the exact dataset snapshot it used.
- Data services layer: Managed databases for feature stores and metadata registries, managed Redis for low-latency feature serving, with access controls defined in version-controlled configuration rather than manually applied per environment.
- Orchestration layer: Pipeline definitions as code, with CI/CD gates controlling promotion between environments. Model registry entries link artifacts to the pipeline runs and dataset versions that produced them.
- Observability layer: Monitoring covering both infrastructure metrics and model behaviour in production, with alerting tied to drift thresholds rather than just system-level health checks.
The interfaces between layers matter as much as the layers themselves. A well-defined storage interface means the compute layer can be changed without touching the data services layer. A well-defined access control model means adding a new environment does not require renegotiating permissions across every service.
Where teams go wrong
The most common failure mode is building the governance layer last, after the platform is already running in production. At that point, retrofitting a model registry, adding data lineage tracking, and enforcing environment parity across infrastructure that was assembled incrementally is a project in itself, often larger than the original build. The second most common failure is underspecifying the training pattern before choosing infrastructure: a platform built for batch monthly retraining will need significant rework if the business later needs daily inference with hourly model refreshes.
Start with the governance requirements. Define what a model promotion looks like before you build the first pipeline. Decide where data lives, under which jurisdiction, and what the audit trail needs to show before you ingest the first training dataset. The infrastructure choices that follow from those decisions are tractable. The choices made in their absence are expensive to undo.